Meet Loora’s New Photorealistic AI Tutor
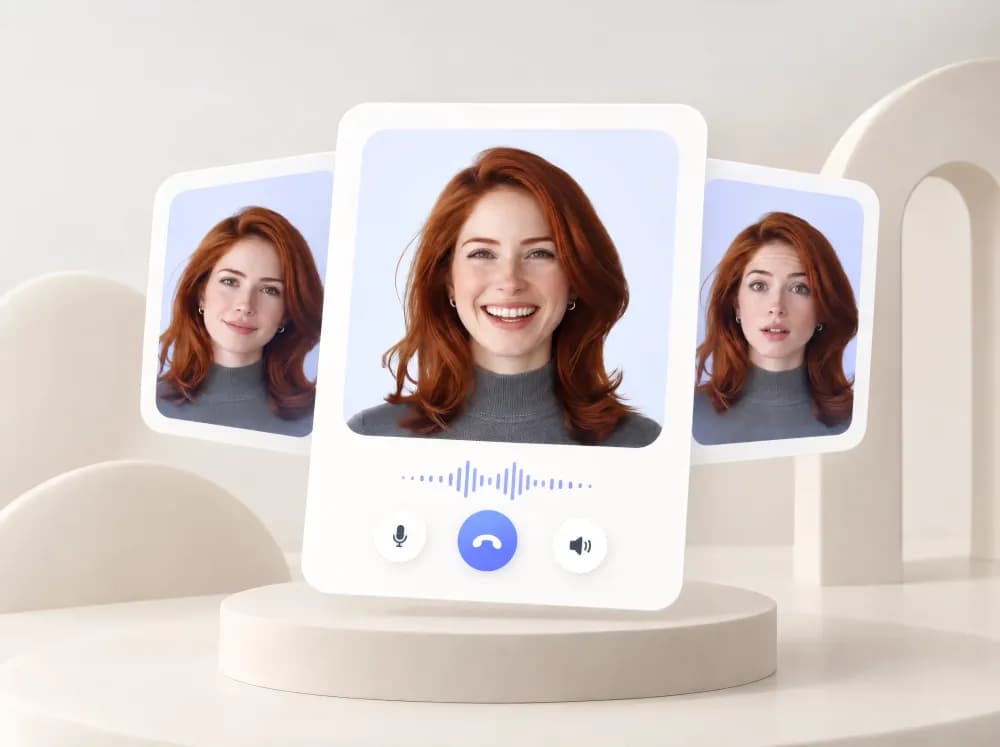
We are excited to roll out Loora’s most realistic conversational experience yet: a photorealistic AI tutor powered by a new state-of-the-art video generation model running entirely on-device in real time for all iOS users, with Android coming soon.
We are excited to roll out Loora’s most realistic conversational experience yet: a photorealistic AI tutor powered by a new state-of-the-art video generation model running entirely on-device in real time for all iOS users.
By generating the avatar locally on mobile hardware rather than relying on cloud video rendering, this update brings the subtle, responsive dynamics of face-to-face conversation into daily English practice.
The Challenge
State-of-the-art video diffusion models deliver extraordinary visual quality, but they remain computationally heavy. Running these models in real time within the strict memory, power, and compute constraints of a mobile phone represents a massive engineering challenge.
For a conversational AI tutor, visual realism alone is not enough: the interaction requires sub-second latency, precise audio-video synchronization, and expressive motion — all happening simultaneously on the user’s device without cloud latency.
Our Approach
Instead of compressing a general-purpose video generation model at the cost of quality, our team engineered a compact diffusion model optimized specifically for real-time interaction.
“Rather than attempting to compress a general-purpose video generation model while preserving all its capabilities, we specialized a compact diffusion model for a narrowly defined task. By leveraging training data specifically tailored to our problem space alongside architectural innovations and hardware-aware optimizations, we developed a system designed for efficient on-device inference.”
— Ben Lustig, AI Team at Loora
Throughout development, we systematically validated key technical assumptions — addressing model size, inference speed, and visual quality directly on commercial smartphones rather than relying on server-side benchmarks.
Technical Benchmarks & Key Results
- On-Device Video Diffusion: Developed one of the first diffusion-based video generation models designed for real-time avatar interactions directly on mobile hardware, without cloud-based rendering pipelines.
- Low-Latency Performance: Achieved an estimated time-to-first-frame latency in the low hundreds of milliseconds on mainstream smartphones, paired with real-time generation throughput.
- High-Fidelity Avatar Experience: Designed to deliver state-of-the-art audio-video synchronization, photorealistic visual quality, natural facial expressions, and dynamic listening cues — including natural turn-taking, smiling, and pausing.
Beyond Realism: Unlocking Speaking Confidence
This update is about much more than visual fidelity for its own sake. For most English learners, the primary barrier to fluency isn’t a lack of vocabulary or grammar — it is the psychological hurdle of speaking out loud.
When an interaction feels lagged or synthetic, learners stay hyper-aware of the technology. By introducing a responsive avatar that listens natively, reacts in real time, and gives learners space to gather their thoughts, Loora creates a low-stakes environment where they feel comfortable expressing themselves, making mistakes, and building real-world speaking confidence.
Availability
The new photorealistic video tutor is live today for all Loora users on iOS. Android is coming soon, and male avatar options will follow in upcoming releases.
Download or update Loora on the iOS App Store to get started.